AI DATA EXTRACTION

Self-adapting pipelines — structured data, at scale

AI-powered web & API scraping

Your team spends hours every week on manual data collection, and the scripts that are supposed to help break every time a source updates. An enterprise analytics team (500–1,000 employees) reduced bad data output by 20–30% and improved validation speed by 30–40% after deploying our Rust-based pipelines; a separate e-sports data client saw 90% workload reduction and 20x faster data ingestion.

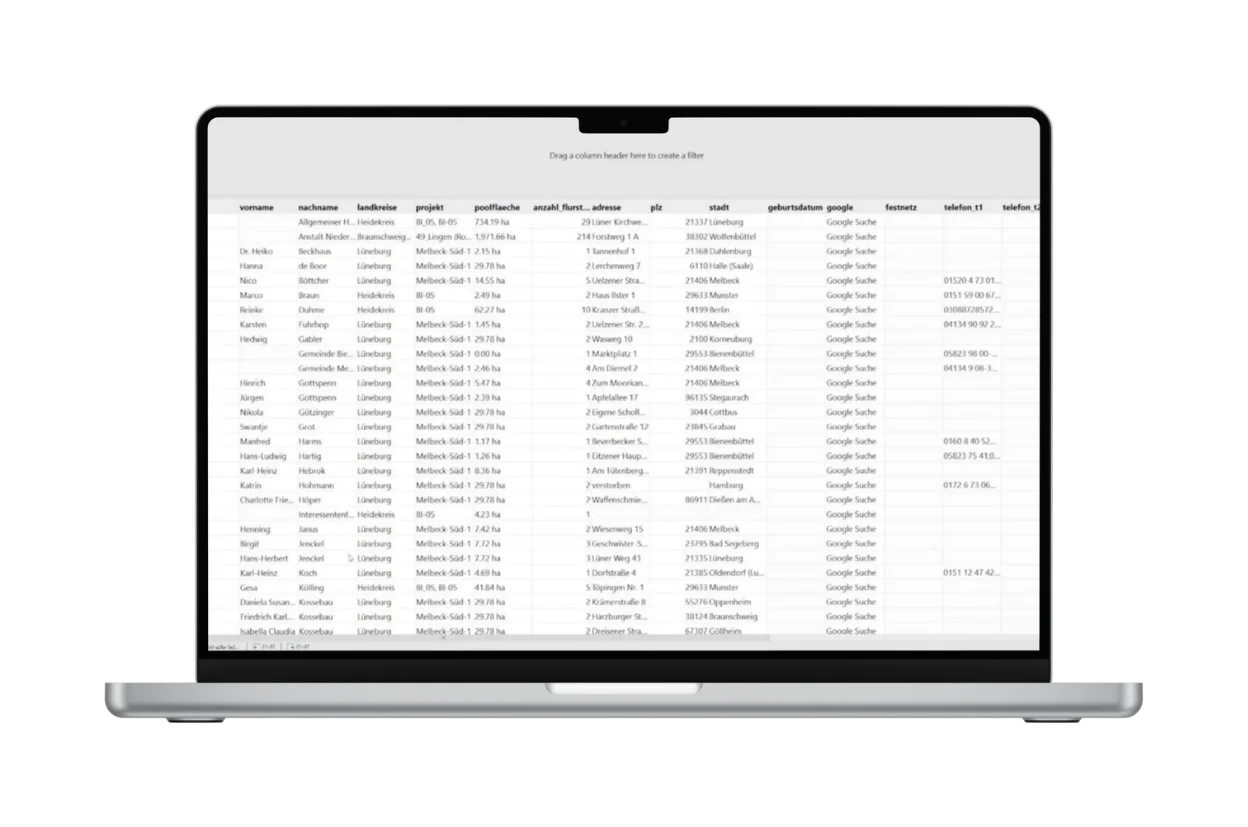
We extract structured data from websites, APIs, and social platforms — clean, formatted, and delivered in the exact structure you need. AI-powered infrastructure handles ML/LLM adaptation, proxy rotation, CAPTCHA solving, and browser fingerprinting — pipelines that self-adapt when sources change, not fragile scripts that break on every update. You own the pipeline: source code, infrastructure config, and docs, with no SaaS lock-in.

We can help you with:

  • Web & E-commerce Scraping
  • Social Media & Public Data Collection
  • API Integration & Raw Data Extraction
  • Price Monitoring & Product Tracking
  • Job Listings, Real Estate, and Business Data
  • Data Cleaning, Formatting & Preprocessing
  • Data Processing automation pipeline
  • Automated Lead Generation
  • and more.

Ready to discuss a reliable data pipeline for your use case? Book your free call!

Technologies we use

  • Python
    Python
  • Selenium
    Selenium
  • Pandas
    Pandas
  • TensorFlow
    TensorFlow
  • n8n
    n8n
  • Rust
    Rust
  • Skyvern
    Skyvern
  • Relevance AI
    Relevance AI
  • Manus
    Manus
  • Airtable
    Airtable
  • Vertex AI
    Vertex AI

Packages

A call about the sources you need read: how they are defended, how often they change, and what a clean record looks like to you.

1 day

We pull a sample from every source you name and show what survives parsing, before a line of automation is written.

7 days

Scoped extraction pipeline — custom scripts, structured output, deployed and automated.

30 days

An extraction platform kept working against sources that change: new formats, new sites, new schemas, and the review loop that catches drift early.

90+ days

Case Studies

FAQ

  • We deliver high-quality, reliable data scraping solutions without requiring constant oversight. We’ve built extraction pipelines handling millions of records across anti-bot protections, rate-limited APIs, and dynamically rendered pages.

  • We rigorously test the scripts to ensure they capture accurate and complete data. Additionally, we can provide a sample of the scraped data for your review before final delivery.

  • If the website updates frequently, we can build a custom script specifically designed to handle that. This will allow you to automatically collect the latest data as often as needed, whether that’s hourly, daily, or on a custom schedule.

  • Skyvern automates browser workflows using AI, adapting to layout changes for tasks like form filling and data extraction, with local or cloud deployment. Relevance AI lets us create AI agents with low-code tools to automate tasks, ensuring security and efficiency across workflows.

  • Yes, instead of a large initial investment, you can opt for a subscription. You pay for a ready-to-use solution with extra guarantees. This spreads out your expenses and includes support — security checks, updates, and issue resolution covered.

  • Scraping projects have a known risk: target sites change layouts. We build resilient selectors and include monitoring in every delivery. Milestone budgets are fixed with clear scope — if a target site requires additional reverse engineering, we flag it with cost impact before proceeding.

  • An enterprise analytics client (500–1,000 employees) embedded our Rust-based data transformation pipelines into their existing PySpark ETL — reducing bad data output by 20–30% and improving validation speed by 30–40%. We automated a web scraping pipeline that reduced manual data collection workload by 90% while cutting API costs by 80%. On a separate project, we built an e-sports data ingestion engine achieving 20x faster throughput using Rust and ClickHouse.

  • Yes. We sign NDAs before any technical discussion begins, on request.

  • You do. IP, source code, architecture docs, and deployment runbooks are fully assigned to you on completion — no vendor lock-in.

  • Yes. Signed contracts with fixed scope per phase. You’re contracting with a registered entity, not an individual.

Book a free call

Consult with our engineering team to define the perfect solution for your needs.

Book a call
30 minutes