COMPUTER VISION

95%+ real-world accuracy — CUDA-optimized, production-deployable

From raw pixels to production intelligence — real-world accuracy at scale.

Manual image analysis doesn’t scale — and adding headcount doesn’t solve it when inference costs are exploding. We build production-ready computer vision that holds 95%+ accuracy under real conditions, processing thousands of frames at under 250ms each. From real-time object detection to pixel-accurate image segmentation, we deliver results that survive production load.

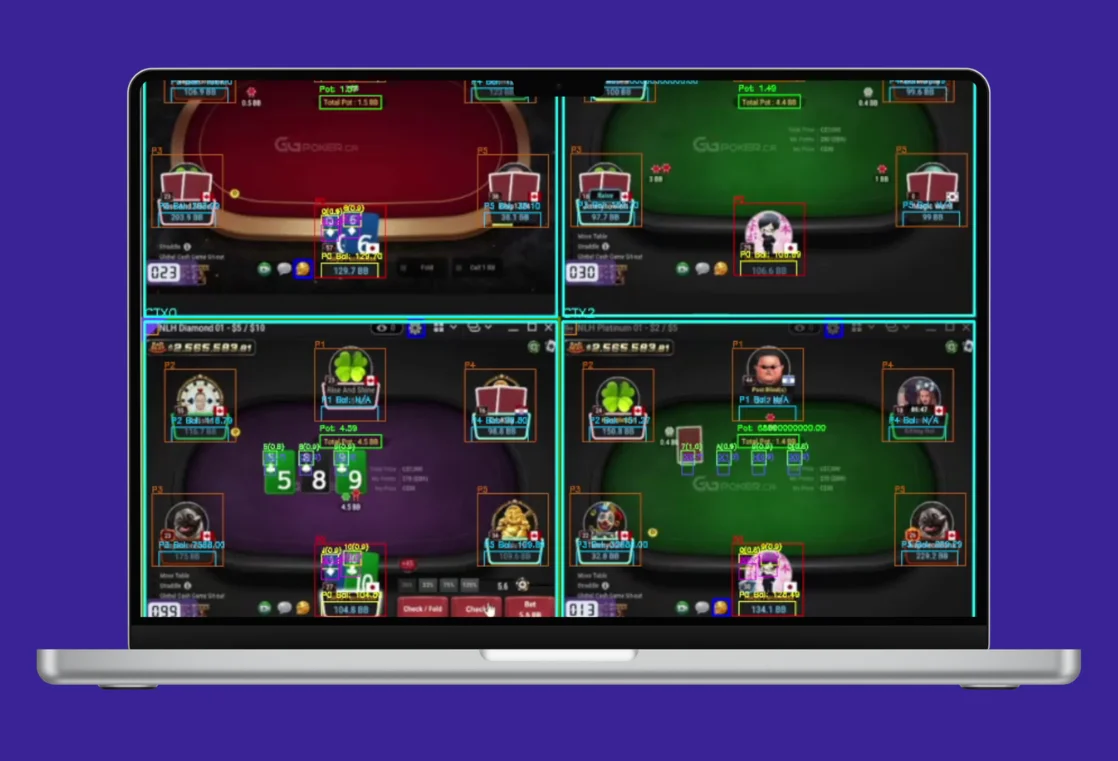
CUDA acceleration, edge TPU optimization, and containerized inference — not Jupyter notebooks. End-to-end: data curation, training, deployment, CI/CD retraining, and drift detection. Proven: manufacturing QA at millions of images daily, and <250ms per-frame across 4 simultaneous feeds on commodity hardware without cloud GPU dependency (Gary Gergen, Tethys Ocean LLC). You own the model and pipeline — containerized, documented, deployable anywhere.

We can help you with:

  • Object Detection & Recognition
  • Image & Video Processing (feature extraction, segmentation, enhancement)
  • Image Segmentation & Classification (CNNs, ViT models, pixel-level analysis)
  • Face & Feature Recognition
  • Pose Estimation & Gesture Recognition
  • AI-Powered Image Generation & Enhancement
  • Handwriting Segmentation
  • Data Prep & Model Selection (Kaggle/HuggingFace datasets)
  • Hardware & Deployment Optimization (CUDA, edge devices, cloud inference)
  • and more.

Ready to discuss a production computer vision pipeline for your use case? Book your free call!

Technologies we use

  • Python
    Python
  • C++
    C++
  • Rust
    Rust
  • PyTorch
    PyTorch
  • TensorFlow
    TensorFlow
  • Keras
    Keras
  • OpenCV
    OpenCV
  • OCR
    OCR
  • CUDA
    CUDA
  • YOLO
    YOLO
  • MediaPipe
    MediaPipe

Packages

A call about the images or video you hold: what has to be recognised, how accurately, and how quickly.

1 day

We label a sample, train a throwaway model on it, and report the accuracy your own data can actually support.

7 days

Scoped CV model — trained on your data, tested, deployed. Inference pipeline included.

30 days

A vision system taken to production and kept there — data collection, retraining, edge deployment and the accuracy figure you measure it by.

90+ days

Case Studies

FAQ

  • We match model complexity (CNN, YOLO, ViT) to your hardware — CUDA GPUs, edge TPUs, or cloud clusters. Then we benchmark for latency, throughput, and power. Our deployment uses containerized microservices, autoscaling, and real-time monitoring for low-latency, cost-effective inference.

  • Not at all. We structure work in clear milestones — R&D, POC, model training, integration, QA — providing digestible progress updates. Our autonomous engineers handle the technical details, while a dedicated manager (or CTO on request) oversees quality and timeline adherence.

  • Each milestone includes cross-QA, code reviews, and performance validation on hold-out sets. We deliver documented code, CI/CD pipelines for retraining, and drift-detection hooks. Ongoing support ensures your models evolve with new data and use-case shifts.

  • We enforce end-to-end encryption (AES-256) for data in transit and at rest, anonymize sensitive features (faces, license plates) on demand, and comply with GDPR and other regional regulations. Models can be deployed on-premises or in private VPCs to ensure full data sovereignty.

  • Yes, we assign a manager who can either communicate with you directly or work behind the scenes. For clients who prefer direct communication with the team, the manager ensures consistency while allowing you to interact directly with developers.

  • ML projects carry uncertainty in model accuracy. We mitigate this by defining success metrics (precision, recall, latency) during Discovery and validating against hold-out datasets at every milestone. If a model isn’t converging, we flag alternatives early — not after six weeks of training.

  • We built a real-time computer vision pipeline processing video at under 250ms per frame across 4 simultaneous feeds. The system reduced operator cognitive load by 75% while logging 10,000+ analysed frames — all running on commodity hardware without cloud GPU dependency.

  • Yes. We sign NDAs before any technical discussion begins, on request.

  • You do. IP, source code, trained models, and deployment runbooks are fully assigned to you on completion — no vendor lock-in.

  • Yes. Signed contracts with fixed scope per phase. You’re contracting with a registered entity, not an individual.

Book a free call

Consult with our engineering team to define the perfect solution for your needs.

Book a call
30 minutes